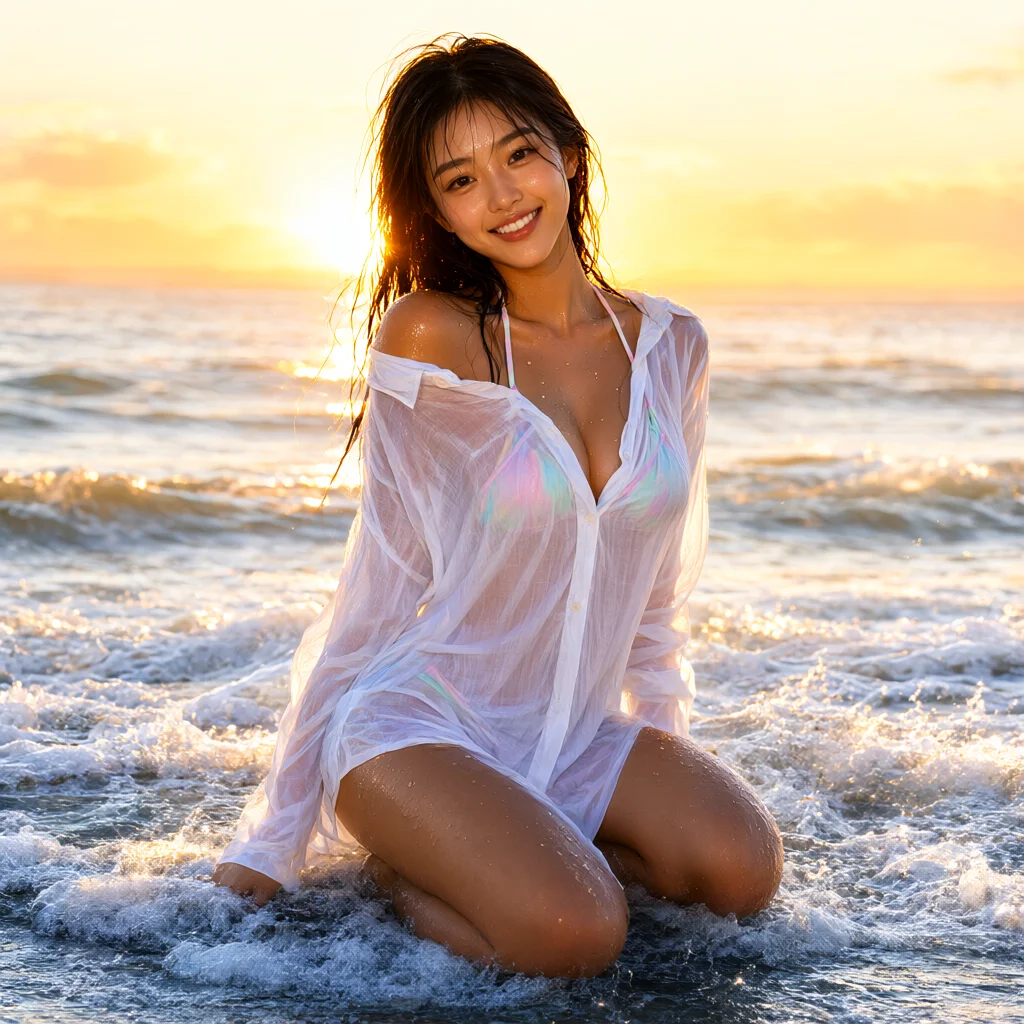
Native GPU execution at full throughput with zero memory swapping.
Flux.1 Dev Spicy Preset: Photorealistic Uncensored Denoising
High-fidelity Flux.1-dev canvas workflow with dual text encoders (CLIP L + T5xxl) and FP8 model precision. Optimized for intricate skin textures, natural folds, and anatomy accuracy.
Reproducible ComfyUI workflow for Flux.1 Dev Spicy Preset: Photorealistic Uncensored Denoising using FLUX.1-dev (FP8 / BF16) at 1024×1024 resolution. Requires minimum 10GB VRAM with sampler euler and scheduler simple (28 steps). Includes 1-click terminal model sync and canvas JSON graph.
Execution DAG Topology Interactive Visualizer
Drag to pan · Scroll to zoom · Hover wiresModel & Asset Setup 1-Click Script
Run in your ComfyUI root:
curl -fsSL https://decomfy.com/api/scripts/fulfill-your-dirty-fantasies-flux-comfyui.sh | bash Loading bash setup script... Loading PowerShell setup script... import modal
app = modal.App("comfyui-fulfill-your-dirty-fantasies-flux-comfyui")
vol = modal.Volume.from_name("comfy-weights-cache", create_if_missing=True)
image = (
modal.Image.debian_slim(python_version="3.11")
.apt_install("git", "wget", "curl", "libgl1-mesa-glx", "libglib2.0-0")
.pip_install("torch", "torchvision", "--index-url", "https://download.pytorch.org/whl/cu124")
.pip_install("transformers", "accelerate", "safetensors", "aiohttp")
.run_commands(
"git clone https://github.com/comfyanonymous/ComfyUI.git /root/ComfyUI",
"cd /root/ComfyUI && pip install -r requirements.txt",
)
)
@app.function(
gpu="T4",
image=image,
volumes={"/root/ComfyUI/models": vol},
timeout=900,
)
def generate():
# Headless serverless execution for FLUX.1-dev (FP8 / BF16)
print("Executing Flux.1 Dev Spicy Preset: Photorealistic Uncensored Denoising on ephemeral T4 GPU...")
return {"status": "success", "slug": "fulfill-your-dirty-fantasies-flux-comfyui"}
runpodctl create pod \
  --name "comfy-fulfill-your-dirty-fantasies-flux-comfyui" \
  --gpu-type "NVIDIA RTX 4090" \
  --image "runpod/comfyui:latest" \
  --volume-in-gb 50 \
  --ports "8188/http"
# ComfyUI Model Batch Ingestion for Flux.1 Dev Spicy Preset: Photorealistic Uncensored Denoising
# Run with: aria2c -i models-fulfill-your-dirty-fantasies-flux-comfyui.txt -j4 -x4
https://huggingface.co/Kijai/flux-fp8/resolve/main/flux1-dev-fp8.safetensors
dir=models/diffusion_models
out=flux1-dev-fp8.safetensors
https://huggingface.co/comfyanonymous/flux_text_encoders/resolve/main/t5xxl_fp8_e4m3fn.safetensors
dir=models/text_encoders
out=t5xxl_fp8_e4m3fn.safetensors
https://huggingface.co/comfyanonymous/flux_text_encoders/resolve/main/clip_l.safetensors
dir=models/text_encoders
out=clip_l.safetensors
https://huggingface.co/diffusers/FLUX.1-vae/resolve/main/diffusion_pytorch_model.safetensors
dir=models/vae
out=ae.safetensors
https://huggingface.co/Heartsync/Flux-NSFW-uncensored/resolve/main/lora.safetensors
dir=models/loras
out=flux_nsfw_uncensored_lora.safetensors Positive Prompt
Negative Prompt
LoRA Adapter Stack 1 Adapters
RTX 4070 Calibrated WeightsRequired Models 5 Models
Field Notes RTX 4070 Benchmark
Flux.1 Dev Photorealism Architecture & Guidance Dynamics: Leverages the 12B parameter FLUX.1 [dev] diffusion transformer with FP8 quantization to comfortably fit within 12GB VRAM cards. Combines DualCLIP conditioning (ViT-L/14 for rapid visual grounding + T5-XXL FP8 for nuanced linguistic comprehension). Enforces strict CFG 1.0 lock because Flux operates with internal guidance embeddings (guidance set to 3.5 via CLIPTextEncodeFlux); setting classic CFG > 1.0 burns out specular highlights and destroys subtle organic skin micro-textures. Chains the artistic realism LoRA adapter for refined physical wet cloth tension, caustic ocean reflections, and authentic skin translucency without cloud filter restrictions.
Frequently Asked Questions FAQ
What GPU and VRAM are required to run Flux.1 Dev Spicy Preset: Photorealistic Uncensored Denoising?
This workflow requires a minimum of 10GB VRAM (recommended 12GB VRAM). Tested and verified on NVIDIA GeForce RTX 4070 (12GB VRAM) at 1024x1024 resolution.
How do I resolve missing custom nodes for this workflow?
You can drop the workflow JSON into our client-side Missing Node Auto-Resolver at https://decomfy.com/resolve/ to detect missing nodes and generate install commands, or run the 1-click terminal setup script provided below.
What quantization format and CLIP encoders should I load for Flux.1 Dev?
This workflow utilizes Flux.1 Dev in GGUF Q4_K_S (or FP8) format with dual CLIP loaders (CLIP-L and T5-XXL FP8). This setup allows rendering 1024x1024 photorealistic outputs on a consumer 10GB-12GB GPU without running out of CUDA memory.
Related ComfyUI Blueprints
View all 28 workflows
Reproduction: Shiba Inu Izakaya Yakitori Chef
Snow White Window: Arched Sunlight & Porcelain Film Aesthetics
Bookshelf Study Portrait: Off-Shoulder Knit & 50mm Bokeh